
⚡
VRAM Orchestrator
Monitor GPU memory in real time. The system unloads inactive text models before heavy image, video, or 3D generation tasks.
Control Ollama, Stable Diffusion Forge, ComfyUI, and Kokoro TTS with automated VRAM orchestration.
Local LLM Server Manager is a cross-platform orchestrator for local artificial intelligence engines. The application operates on Windows and Linux. The system coordinates Large Language Models, image generation, 3D mesh reconstruction, video synthesis, and speech generation.
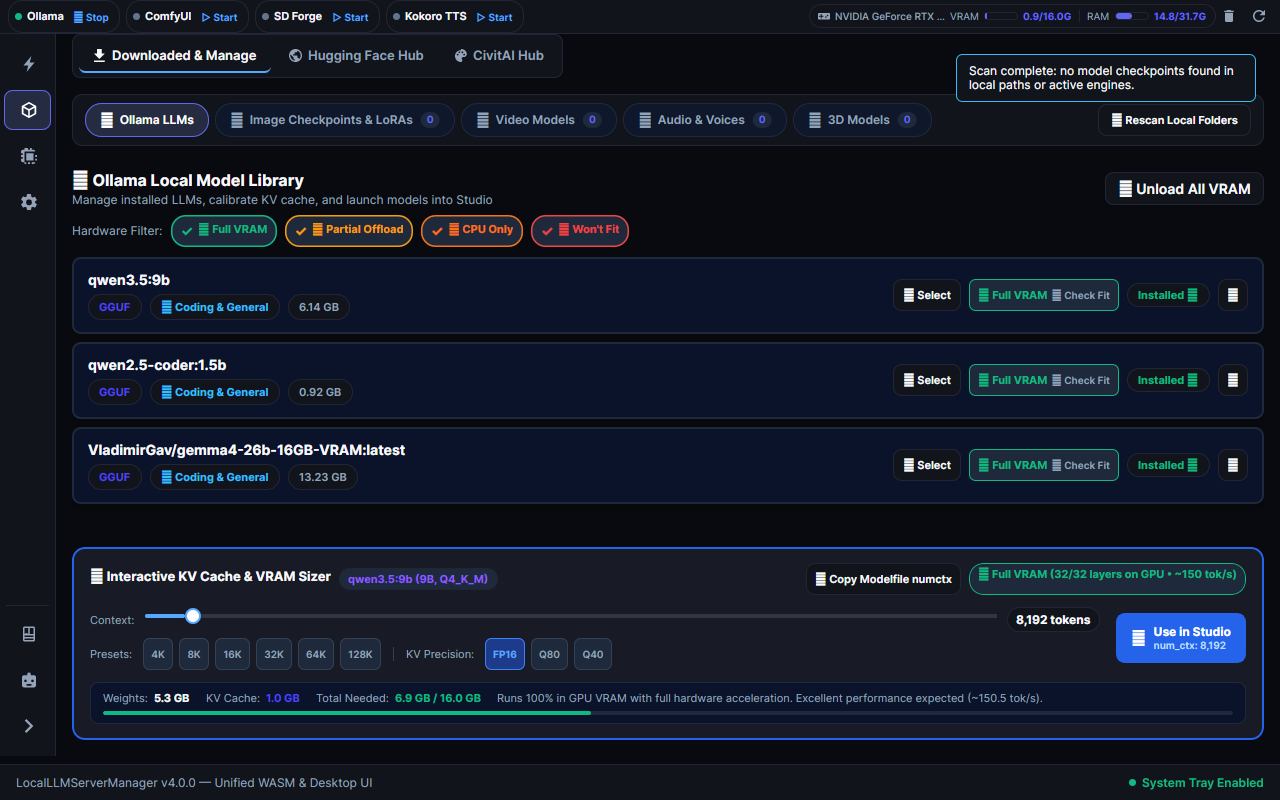
| Layout Section | Primary Function | Active Elements |
|---|---|---|
| Telemetry Header & Ribbon | Live Hardware & Engine Monitoring | GPU name, real-time VRAM allocation bar, interactive engine status cards (Ollama, ComfyUI, SD Forge, Kokoro TTS) with live status dots, tooltips, and click-to-manage toggles. |
| Activity Rail | Workspace Domain Navigation | Primary navigation across Models (Local, Hugging Face, CivitAI), Multimodal Studio, Can I Run It (Hardware Fit), and Settings, plus Copilot and Documentation sidebar launcher buttons. |
| Fluid Studio Canvas & Dock | Creative Generation Center | Modality selector bar (🎨 Image, 💬 Text, 🎬 Video, 🧊 3D Mesh, 🎙️ Audio), generous center stage preview canvas, style preset bar, and bottom creative prompt dock with parameters flyout (⚙️ Settings). |
| Docked Copilot & Knowledge | Unified Assistant & Guides Sidebar | Right-side docked sidebar hosting interactive Copilot AI chat (🤖 Copilot) and procedural documentation guides (📖 Knowledge) with seamless tab switching, magnetic companion pop-out, and contextual prompt transfer. |
| Companion Windows | Floating Multi-Window System | Detachable Documentation and AI Assist windows with magnetic flank docking and lockstep tracking. |
5246).Explore the documentation guides to set up and operate your local AI stack: